What SRE taught me about running AI agents
AI agents are not chatbots, they are production software. Eight rules my teams follow to build and run agentic systems, taken from SRE and software engineering.
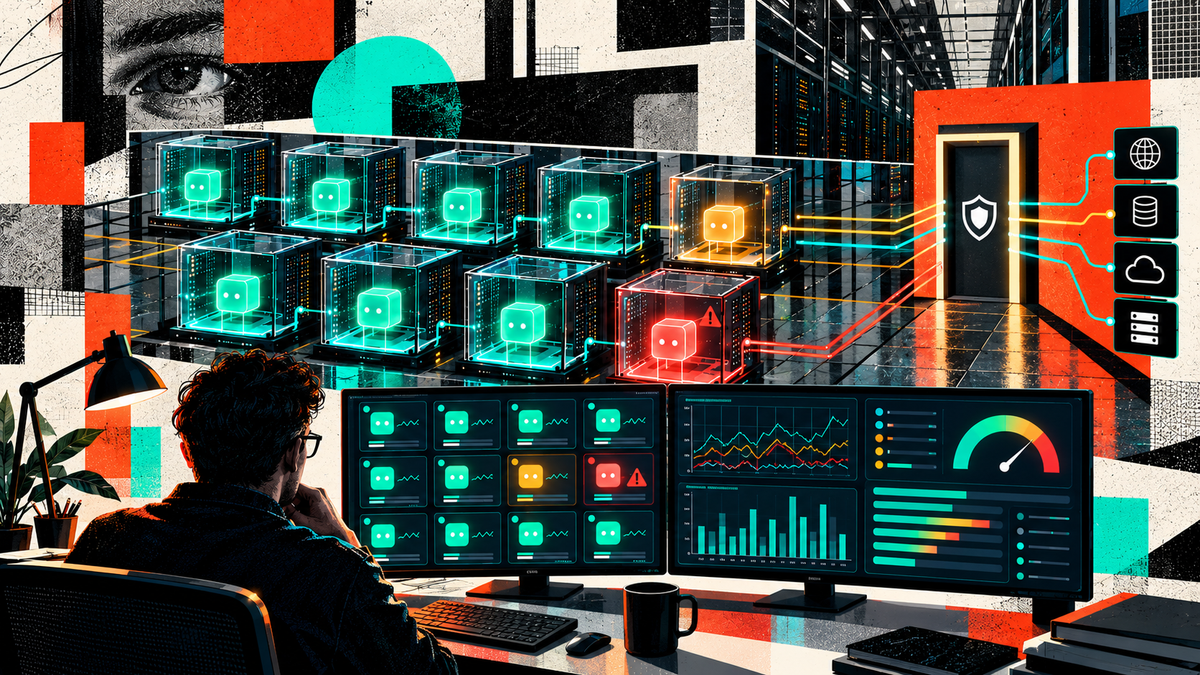
I started my career as a system administrator. Later I was DevOps engineer, then I built and led an SRE organisation. Today, together with my teams, we spend a lot of time designing agentic systems and implementing them to automate complex business functions. And I see the same thing again and again: people think agents need completely new rules. In my experience, they mostly need the old rules from SRE and software engineering, applied a bit differently.
An AI agent is not a chatbot. If an agent writes code, closes tickets or prepares reports, it is a production system. It has credentials, it spends money, and it makes decisions. So we should build and run it like production software.
There is one big difference. Servers fail loudly: they crash, they time out, the disk is full, you get an alert. Agents fail quietly. The agent finishes the task, says "done", and the result is wrong. Nobody gets paged. Keep this in mind for everything below.
1. Agents are software, so run them like software
Production software does not run on somebody's laptop. Agents should not either. They should run on servers or virtual machines in the cloud and work on their tasks 24/7. A simple test: does your agent keep working when you close your laptop? If not, it is a demo, not a production system.
2. Keep the blast radius small
There is also a safety reason. An agent running on your laptop can delete files, install packages you don't want, or break your environment. On a separate server it cannot touch any of this.
With infrastructure we learned to isolate things, so one failure does not take down everything. With agents it is even more important, because you can trick an agent with the right text, and you cannot do that with a server. What works for us: one agent, one isolated environment, its own identity, and only the access a person gave it. If it needs more access, it asks, and a person gives it for limited time. When something goes wrong (and it will), you lose one task on one machine, not your whole environment.
3. Security rules apply to agents too
We don't let software talk to any address on the internet, and agents should be treated the same way. Limit them with network rules. Send everything that goes out through one controlled exit, where it is checked and recorded. Monitor agent machines and scan them with the same security tools you use for the rest of your systems. An agent is one more workload for your security team, not an exception.
4. Many small agents, not one big agent
It is tempting to build one big agent that can do everything. At the start it even looks simpler. But such an agent is very hard to test, upgrade and maintain.
We already solved this problem in software engineering with microservices, and the same approach works for agentic systems. Build them from small groups of agents, each responsible for one specific function. Each group has a clear interface and a contract: what input it accepts and what output it gives back. Then you can test one group alone, upgrade it without touching the others, and replace it when something better appears.
5. Agentic Systems as Code
We had Infrastructure as Code. Now it is time for Agentic Systems as Code. All agent configuration should live in a repository: prompts, skills, context, integrations with other agents, permissions and access settings. Then you can review every change, roll it out to a few agents first, roll it back in one step, and reuse good parts across many systems. If people change prompts directly in a chat window, it is the same as changing production servers by hand. We stopped doing that many years ago for good reasons.
6. Use a framework, don't build every agent by hand
Building agents by hand is fine for the first few. But after that you start repeating yourself and reinventing the wheel every time. Each engineer builds agents in a different way, and nobody else can easily understand or reuse them.
What helps is a framework, in the best case something like a programming language for agents. You define building blocks once and then build agentic systems from these blocks, the same way we build software from objects and classes in object-oriented programming. This also solves a team problem. When many people build agentic systems together, you need standards in the team, and later in the whole company, for how to build complex agentic systems: which architecture to use, what style and approach to follow, which principles are not negotiable, and which tools and frameworks everybody uses. Without such standards, every team builds agents its own way, and after one year you have a zoo of systems that nobody can support. A framework makes these standards part of the code, not a document nobody reads. New engineers follow them automatically, simply by using the framework.
7. Measure the work, and give autonomy by data
Your latency and error dashboards will be green when the agent gives a confident wrong answer. So you need to monitor the work, not only the process. Log what the agent changed, which systems it called and how much it spent. Count every token per agent, per task and per team. Finance will ask you about it, probably before security does.
Then use the old SRE idea of an error budget. Measure something real, for example how many tasks were accepted without rework. If the agent is well inside the target, give it more freedom. If it burns the budget, take freedom back. Trust should be based on data, not on the last good demo.
8. On-call and postmortems still apply
Who gets the call when an agent is in a loop at 3am and calls the same API ten thousand times? You need limits on spend and rate that stop it before a human must wake up, and a kill switch for one agent and for all of them. Test this kill switch regularly, like you test backup restore.
And when an agent does something bad, the first reaction is usually to blame the model. In my experience, it is almost never the model. Today's models are very advanced and capable. The problem is usually in how we, humans, designed the agentic system. We gave the agent not enough context or knowledge. We gave it tools that did not work properly, or too much access. We put too few controls around it. And honestly, humans are quite bad at explaining things and expressing ideas clearly, so the agent often does exactly what we said, not what we meant.
So a good postmortem does not ask "why did the model do this?" It asks "why did our system allow it?" and "what did we miss or do wrong to get this result?" Which context was missing, which tool was broken, which access was too wide, which check or alert was not there? These things you can fix, and every next agent gets the fix through code. And it is still blameless: we look for the gap in the design, not for the person to blame.
My conclusion
Agents are a new type of workload, but the basics did not change. The teams that will run agents well are not the teams with the smartest prompts. They are the teams that treat agents as production software: run them on servers, isolate them, secure them, build them from small parts, keep them in code, use a framework, measure them, and learn from incidents.
We built all of these ideas into Gigatokens Conductor, the agentic platform we created at Gigatokens, a Behavox company. Every agent runs on its own machine. Every outbound call goes through one controlled door, Stormgate, our security system, where the call is inspected and the decision is recorded. An agent has only the access a person gave it, and when it needs more, it asks. Gigatokens Conductor also has its own framework for building agentic systems from building blocks, and I will write about it in the next articles. We first built Conductor to run our own agents, and now it is available to other companies too. You can read more at gigatokens.ai.
In the next article I will write about digital twins: why I think software engineering needs a copy of the real world for agents to practise in. Subscribe if you want to get it by email.
Aleksei Shishkin (Alex Post) is VP Technology Operations at Behavox and founder of Gigatokens, a Behavox company. He builds AI end to end, from GPUs and inference to agentic systems that automate business functions.